
Quick answer
An incident response plan (IRP) is a documented procedure that tells your team exactly what to do when a cybersecurity incident happens. Without one, decisions get made under pressure by whoever's awake — usually badly.
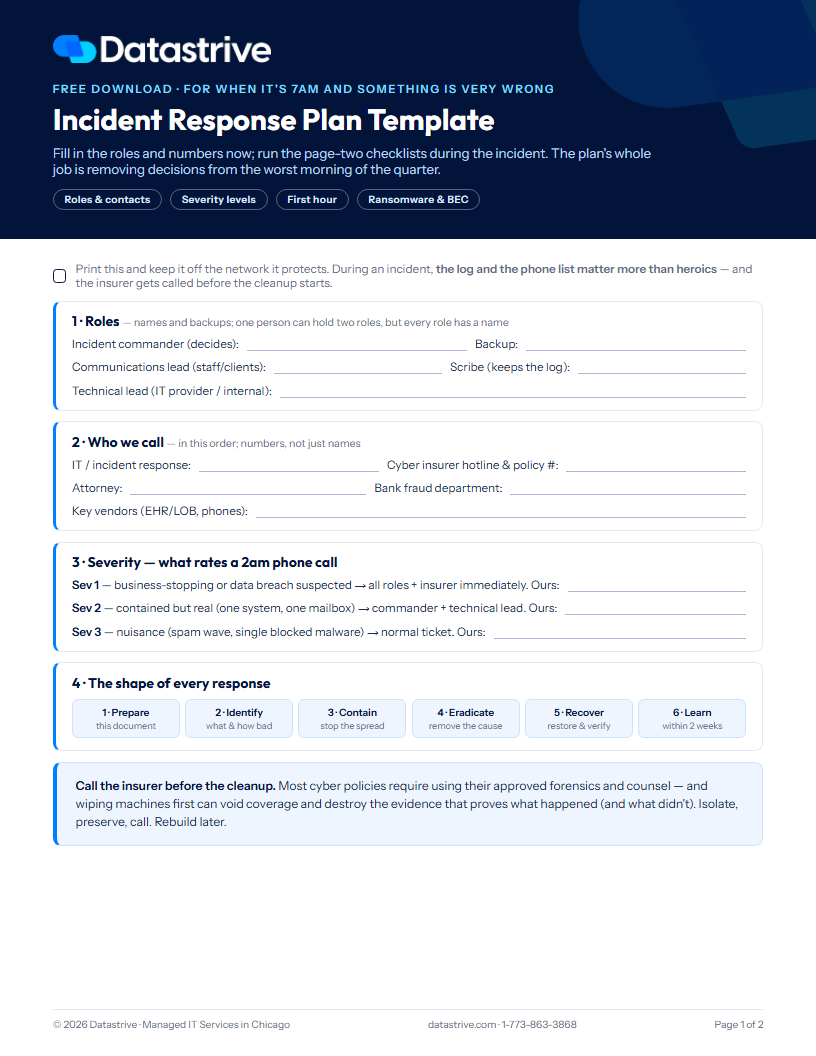
A complete IRP for a small or mid-sized business should cover six things:
| Section | What it answers |
|---|---|
| 1. Plan ownership & review | Who owns this plan, and when does it get updated |
| 2. Incident response team | Who does what during an incident, with primary and backup contacts |
| 3. Severity definitions | How to classify an incident so the response matches the threat |
| 4. Phases & procedures | Step-by-step actions for each phase: detect, contain, eradicate, recover |
| 5. Communications | Who to notify, when, and what to say (internal, customers, regulators, law enforcement) |
| 6. External resources | Cyber insurance, MSP, legal counsel, forensics — contacts pre-arranged before you need them |
The full template is below — designed to be copied into a Word doc, customized for your business, and signed off by leadership. Skip down if you just want the template, or read on for the framework that makes it work.
What an incident response plan actually is
The term gets used to describe everything from a one-page checklist to a 50-page compliance document. The version that's actually useful is closer to the checklist — a clear, role-based playbook that someone can pick up at 2 AM and follow.
An effective incident response plan does three things:
- Tells your team who's in charge. Incidents go badly when nobody owns the response. The plan names a primary, a backup, and an escalation path.
- Defines what counts as an incident. A single phishing email isn't the same as ransomware on the file server. The plan classifies severity so the response matches.
- Specifies the actions for each phase. Detect, contain, eradicate, recover, document. Specific actions, not principles.
Anything else — frameworks, theory, regulatory citations — belongs in the appendix. The body of the plan needs to be operational.
Who actually needs an incident response plan
Four common triggers force most SMBs to write one:
1. Cyber insurance application or renewal
Cyber insurance carriers ask whether you have a documented IRP. Increasingly, they require a specific format and won't issue or renew coverage without one. Carriers also want to see evidence of testing — typically an annual tabletop exercise.
2. Vendor security questionnaire
If you sell to mid-market or enterprise customers, you'll get questionnaires (SIG Lite, CAIQ, custom internal versions) asking for your IRP. "We don't have one" disqualifies you from contracts. A well-built IRP, or even a redacted version of it, gets you past this gate.
3. Compliance requirements
HIPAA, PCI DSS, SOC 2, CMMC, ISO 27001 — all require an incident response capability with documentation. Specific requirements vary, but the underlying expectation is the same: a written plan, a defined team, evidence of testing, and a record of incidents handled.
4. The first real incident
The honest one. Many SMBs write their first IRP after handling a real incident badly — wrong people on the call, wrong decisions made, no record of what happened, regulators or customers asking questions afterward. The plan you write at that point is shaped by what just hurt you. Better to write it before.
The six phases of incident response
Most incident response frameworks follow some version of the NIST SP 800-61 model. The phases:
Phase 1: Preparation
Everything you do before an incident — having the plan, training the team, deploying detection tools, maintaining backups, running tabletop exercises. The single highest-leverage phase, because the quality of your preparation determines how the rest of the response goes.
Phase 2: Detection & Analysis
How you discover an incident is happening and confirm what it is. Detection comes from monitoring tools (EDR, SIEM, email security alerts), user reports ("my file got encrypted"), or external notification (a customer or law enforcement contacts you). Analysis is the triage — figuring out scope, severity, and what to do next.
Phase 3: Containment
Stop the bleeding. Disconnect compromised systems, disable affected accounts, block malicious IPs at the firewall. Containment has two sub-phases: short-term (immediate, sometimes scrappy) and long-term (sustainable, documented).
Phase 4: Eradication
Remove the threat. Wipe and reimage compromised endpoints, rotate credentials, patch the vulnerability that allowed the incident, remove persistence mechanisms (scheduled tasks, registry keys, malicious accounts).
Phase 5: Recovery
Restore normal operations. Bring systems back online, restore from clean backups, monitor closely for re-infection, verify that business processes are functioning.
Phase 6: Post-Incident Activity
The retrospective. What happened, what went well, what went badly, what needs to change. This phase is where most organizations skip steps — and it's where the lessons live. A formal lessons-learned meeting within 2 weeks of the incident is the bare minimum.
Section-by-section walkthrough
What goes in each part of the template, and why.
Plan ownership and review
Names the IRP owner (typically the head of IT or the CISO if you have one), the executive sponsor (CEO, COO, or CFO), and the review cadence (annual minimum, plus after every significant incident or organizational change). Without an owner, the plan goes stale; without an executive sponsor, the plan has no authority during a real incident.
Incident response team roster
Lists every role that may be activated during an incident — IT lead, security lead, executive sponsor, legal, communications, HR. Each role has a primary person and a backup, with current phone numbers (cell and work) and email addresses. External roles too: MSP, cyber insurance carrier, outside counsel, forensics firm.
The roster is the most operationally critical section. When the email server is compromised, you need cell phone numbers — not @yourcompany.com addresses.
Severity definitions
A simple classification scheme so the response matches the incident. Most SMBs use 3 or 4 severity levels:
| Severity | Examples | Response |
|---|---|---|
| Critical (Sev 1) | Ransomware actively encrypting; large-scale data exfiltration; complete authentication outage | Full team activation immediately; executives notified within 1 hour |
| High (Sev 2) | Confirmed malware on endpoints; unauthorized access to sensitive systems; targeted phishing succeeding | IT and security leads activated; executives notified within 4 hours |
| Medium (Sev 3) | Single-user phishing; isolated malware caught by EDR; suspicious access patterns | IT lead investigates; report at next standup |
| Low (Sev 4) | Routine spam; failed login attempts; minor policy violations | Logged and monitored; no activation |
Phase procedures
Specific actions for each of the six phases, scoped to your environment. Generic "follow security best practices" language doesn't help during an incident. Specific actions like "run Disable-CSAccount in PowerShell to disable a compromised user" do.
Communication plan
Who gets notified during an incident, in what order, and what they're told. Includes:
- Internal: executives, employees, board (when applicable)
- Customers: when notification is required, who drafts the message, who approves
- Regulators: HIPAA's 60-day rule, PCI DSS's immediate notification, state breach laws (varies — California is fastest), SEC's 4-day rule for public companies
- Law enforcement: FBI for major incidents (especially ransomware); local police for physical break-ins
- Cyber insurance: notification within hours is typically required for coverage
- Public/media: if applicable, who handles statements
External resources
Pre-arranged contacts for the help you'll need. Don't try to find a forensics firm during an incident — have one on retainer or at least introduced. Same for outside counsel familiar with breach response and your cyber insurance carrier's claims line.
The full template
Below is a complete IRP template. Copy this entire section into a Word doc, fill in the bracketed values, and you have a starting plan. Customize for your industry (notes after the template).
[Company Name] Incident Response Plan
Document version: [1.0]
Effective date: [Date]
Plan owner: [Name, Title, Email, Cell]
Executive sponsor: [Name, Title, Email, Cell]
Review cadence: Annually, and after every Sev 1 or Sev 2 incident
Last reviewed: [Date]
1. Purpose & Scope
This Incident Response Plan defines how [Company Name] detects, responds to, and recovers from cybersecurity incidents affecting our information systems, data, or operations. It applies to all employees, contractors, and third parties with access to [Company Name] systems and data.
2. Definitions
Event: Any observable occurrence in a system or network.
Incident: An event that violates security policies or threatens confidentiality, integrity, or availability of systems or data.
Breach: An incident involving confirmed unauthorized access to or disclosure of regulated data.
3. Incident Response Team
Internal roles:
- IT Lead (primary): [Name, Cell, Email]
- IT Lead (backup): [Name, Cell, Email]
- Security Lead: [Name, Cell, Email]
- Executive Sponsor: [Name, Cell, Email]
- Legal Counsel (internal): [Name, Cell, Email] or "external" — see below
- Communications Lead: [Name, Cell, Email]
- HR Lead: [Name, Cell, Email]
External roles:
- Managed services provider: [MSP name, account number, 24/7 hotline, account manager cell]
- Cyber insurance carrier: [Carrier, policy number, claims hotline, broker cell]
- Outside counsel (breach response): [Firm, attorney name, cell, email]
- Forensics firm (on retainer or pre-arranged): [Firm name, primary contact, cell]
- Law enforcement (FBI): Local Field Office at [phone]; IC3 at ic3.gov for online complaints
4. Severity Classification
Severity 1 (Critical): Ransomware actively encrypting systems; large-scale data exfiltration; complete authentication outage; threats to life safety. Activation: full team within 1 hour.
Severity 2 (High): Confirmed malware on multiple endpoints; unauthorized access to sensitive systems; targeted phishing succeeding; partial production outage. Activation: IT and security leads within 4 hours.
Severity 3 (Medium): Single-user phishing succeeding; isolated malware caught by EDR; suspicious but unconfirmed activity. Activation: IT lead investigates; reported at next standup.
Severity 4 (Low): Routine spam; failed login attempts; minor policy violations. Activation: logged in ticketing system; no team activation.
5. Phase 1 — Preparation (Ongoing)
- Maintain current asset inventory of systems and data
- Maintain offsite, immutable backups tested at least quarterly
- Deploy and monitor EDR on all endpoints
- Deploy and monitor email security and DNS filtering
- Conduct security awareness training quarterly
- Conduct full tabletop exercise of this plan annually
- Review and update this plan annually
6. Phase 2 — Detection & Analysis
Detection sources: EDR alerts, email security alerts, firewall/IDS alerts, user reports (via [helpdesk channel]), MSP monitoring, external notification.
On detection, the receiving party will:
- Document time of detection, source, and initial observation
- Open an incident ticket in [ticketing system]
- Notify the IT Lead immediately if observation is consistent with Sev 1 or Sev 2
- Begin initial scope assessment: how many systems, what data, what users
- Classify severity using Section 4
- If Sev 1 or 2, activate the team per Section 7
7. Phase 3 — Containment
Short-term containment:
- Isolate affected endpoints from the network (disconnect, not just power-down)
- Disable compromised user accounts in [identity provider]
- Block malicious IPs at the firewall
- Preserve evidence: take memory snapshots, capture logs, document timestamps
Long-term containment:
- Deploy temporary patches or compensating controls
- Increase monitoring on adjacent systems
- Continue evidence preservation
8. Phase 4 — Eradication
- Wipe and reimage compromised endpoints from known-clean baseline
- Rotate credentials for all affected accounts (and any accounts that may have been observed in memory)
- Patch the underlying vulnerability that allowed the incident
- Remove malware persistence mechanisms (scheduled tasks, services, registry keys, rogue accounts)
- Validate eradication via fresh scan of all affected systems
9. Phase 5 — Recovery
- Restore systems from clean backups (verified pre-incident date)
- Bring systems online incrementally, monitoring for re-infection
- Re-enable user accounts after credential rotation and MFA verification
- Confirm business processes are functioning
- Maintain heightened monitoring for [30 days minimum]
10. Phase 6 — Post-Incident Activity
- Hold formal lessons-learned meeting within 2 weeks of incident closure
- Document the incident: timeline, root cause, response actions, outcomes
- Identify and assign action items to prevent recurrence
- Update this plan to reflect lessons learned
- Brief executive sponsor and (if applicable) board
11. Communication Plan
Internal notification timing:
- Sev 1: executives within 1 hour, employees within 24 hours via [channel]
- Sev 2: executives within 4 hours, affected employees within 24 hours
- Sev 3-4: routine reporting via security operations report
External notification (Sev 1-2 only, after legal review):
- Customers: [Communications Lead] drafts; [Executive Sponsor] approves; legal review required if regulated data is involved
- Regulators: Notify within timelines required by applicable regulations (HIPAA 60 days from discovery; PCI DSS immediately; state breach laws vary; SEC 4 days for material incidents at public companies)
- Cyber insurance: Notify within [hours specified in your policy] of discovery; required for coverage
- Law enforcement: FBI Local Field Office for ransomware, BEC, or significant data theft; notify after consulting outside counsel
- Media: No public statements without [Executive Sponsor] approval; refer media inquiries to [Communications Lead]
12. Plan Review & Approval
This plan was reviewed and approved by [Executive Sponsor] on [Date].
Next scheduled review: [Date].
Tabletop exercise schedule: [Quarterly / Annually].
Industry-specific customization
The template above is a starting point. Three common industries need additional language:
Healthcare (HIPAA)
Add a specific Breach Notification section that references the HIPAA Breach Notification Rule. Key requirements: 60-day notification to affected individuals (or sooner if state law is stricter), notification to HHS, notification to media for breaches affecting 500+ individuals in a state. Reference the Privacy Officer and Security Officer roles by name. Add documentation of risk assessment for any incident involving PHI to determine breach status.
Card payments (PCI DSS)
Add a specific section for cardholder data environment (CDE) incidents. Notification to the acquiring bank is required immediately upon confirmed compromise of cardholder data. Forensic investigation by a PCI Forensic Investigator (PFI) is required for compromises involving more than [threshold defined in your merchant agreement]. Reference the PCI Security Standards Council's incident response guidance.
Professional services (SOC 2, client contracts)
Add explicit reference to client notification obligations from master services agreements (MSAs). Many B2B contracts require notification within 24-72 hours of confirmed incidents involving client data — earlier than most regulatory requirements. Maintain a list of which clients have which notification clauses, with contract reference numbers.
How to test the plan
An incident response plan is worthless until it's tested. The minimum cadence: one tabletop exercise per year. The realistic cadence: quarterly tabletops, plus a longer simulation annually.
Tabletop exercise format
A tabletop exercise is a discussion-based walk-through of a hypothetical scenario. The team gathers (in person or remote), a facilitator presents the scenario in stages, and participants describe what they would do. No actual systems are touched.
A typical 90-minute tabletop:
- 0–15 min: Brief on scope, objectives, ground rules
- 15–60 min: Walk through the scenario in 3–4 injects (initial detection, escalation, containment decision, customer notification decision)
- 60–80 min: Hot wash — what worked, what didn't, what was confusing
- 80–90 min: Action items assigned with owners and dates
Realistic scenarios for SMB tabletops
- Ransomware on the file server discovered Friday at 5 PM
- Phishing-driven business email compromise (BEC) intercepting an invoice payment
- Accidental data exposure (employee sends a customer list to a personal Gmail account)
- Stolen laptop with sensitive data, full disk encryption status unknown
- Vendor breach exposing your data (e.g., your payroll provider notifies you they had an incident)
Document every tabletop. Cyber insurance carriers, auditors, and customer security reviewers will ask for evidence — typically the date, scenario, participants, and action items.
Common mistakes to avoid
Eight failure patterns we've seen in real incident response engagements:
- The plan is too long to use during an incident. A 50-page plan that nobody can find the right section in is worse than a 5-page plan that gets to the point.
- The team roster has email-only contacts. When the email server is compromised, you need cell phones. Update the roster quarterly.
- No off-network copy of the plan. If your file server is encrypted, you can't read the plan stored there. Keep a printed copy and an offline-accessible digital copy.
- Severity classifications that don't match real incidents. If everything is "high severity," nothing is. Calibrate the levels to your actual environment.
- No defined approver for customer notifications. The drafting/approval/sending chain freezes during an incident if nobody knows who has the authority. Spell it out.
- External resources arranged after the incident starts. Forensics firms, breach counsel, and PR support need to be lined up in advance. Mid-incident is the worst time to be onboarding a new vendor.
- No annual review. Plans go stale fast — people leave, tools change, vendors change. The plan that was perfect 18 months ago has wrong contacts and missing systems.
- Tabletops as theater. If the exercise is scripted to make the team look good, it's worthless. Real tabletops surface real problems — that's the point.
Getting started
If you're starting from zero, the realistic sequence:
- Week 1: Copy the template above into a Word doc, fill in the bracketed values, get an executive sponsor signed off
- Week 2: Confirm external resources (cyber insurance, MSP, outside counsel) — get their 24/7 contact information into the document
- Week 3: Brief the incident response team on their roles; make sure everyone has a copy and knows where to find it offline
- Week 4–6: Run a first tabletop exercise; document the action items; refine the plan based on what came up
- Quarterly thereafter: Tabletop exercises with rotating scenarios; annual full review of the plan
If you'd like help building or refining your incident response plan — including running the first tabletop exercise with your team — we're happy to get on a call. Datastrive runs incident response engagements for Chicago-area businesses across healthcare, legal, financial services, and other regulated industries.